 |
Jinlong Li
Pushing a long-termist, strike the tough yet right things correctly. |
Biography
I am a visiting PhD student at the Computer Vision and Geometry Group (CVG), ETH Zurich, Switzerland, under the supervision of Prof. Marc Pollefeys, and a PhD student at the Multimedia and Human Understanding Group (MHUG), University of Trento, Italy, under the supervision of Prof. Nicu Sebe. Previously, I was a research scientist in computer vision at Meituan, working closely with Dr. Lin Ma and Dr. Zequn Jie on label-efficient 2D/3D/4D detection and segmentation. Before that, I received a dual B.Sc. degree (major: Applied Physics) and an M.Sc. degree in Computer Science from Shenzhen University.
Research Interest
I work on computer vision and deep learning. My recent research aims to build machines that can see, reason about, and interact with the geometric and physical world through a unified end-to-end paradigm built on representation and generative learning. Topics I am exploring include:
- Multi-Modal Perception, Reasoning and Planning
- Spatial Foundation Models
- Generative Models
- Label-Efficient Learning in 2D, 3D and 4D
News
- 2026.09: Two papers, OneVL and LECDrive (VLA-based autonomous driving), got accepted by NeurIPS 2026! Congrats to all co-authors!
- 2026.07: One paper, Stable-ST, got accepted by IJCV 2026! Congrats to Dong!
- 2026.05: We released OneVL, the first latent CoT method to surpass explicit CoT in autonomous driving trajectory planning while matching answer-only inference latency, via a unified VLA and World Model framework.
- 2026.02: Our work AOT got accepted by CVPR 2026! Congrats to all co-authors!
- 2025.02: Our works CUA_O3D and FisherTune got accepted by CVPR 2025! Congrats to all co-authors!
- 2024.09: Our work LESS got accepted by NeurIPS 2024!
- 2024.07: Our work RKP got accepted by ACM MM 2024!
- 2024.07: Our work 3DSS-VLG got accepted by ECCV 2024!
Earlier news
- 2023.02: One paper got accepted by Neurocomputing 2023!
- 2022.09: Our work ESOL got accepted by NeurIPS 2022!
- 2022.02: Our work PPL got accepted by TMM 2022!
PrePrints
 |
A Survey on Post-training of Multimodal Large Language Models
|
 |
3D Weakly Supervised Semantic Segmentation via Class-Aware and Geometry-Guided Pseudo-Label Refinement
|
 |
Orthogonal Projection Subspace to Aggregate Online Prior-knowledge for Continual Test-time Adaptation
|
 |
Feature Compression for Vision-Language Models: Query-Driven Encoding in Bandwidth-Constrained Environments
|
 |
Enhancing Robustness of Vision-Language Models through Orthogonality Learning and self-Regularization
|
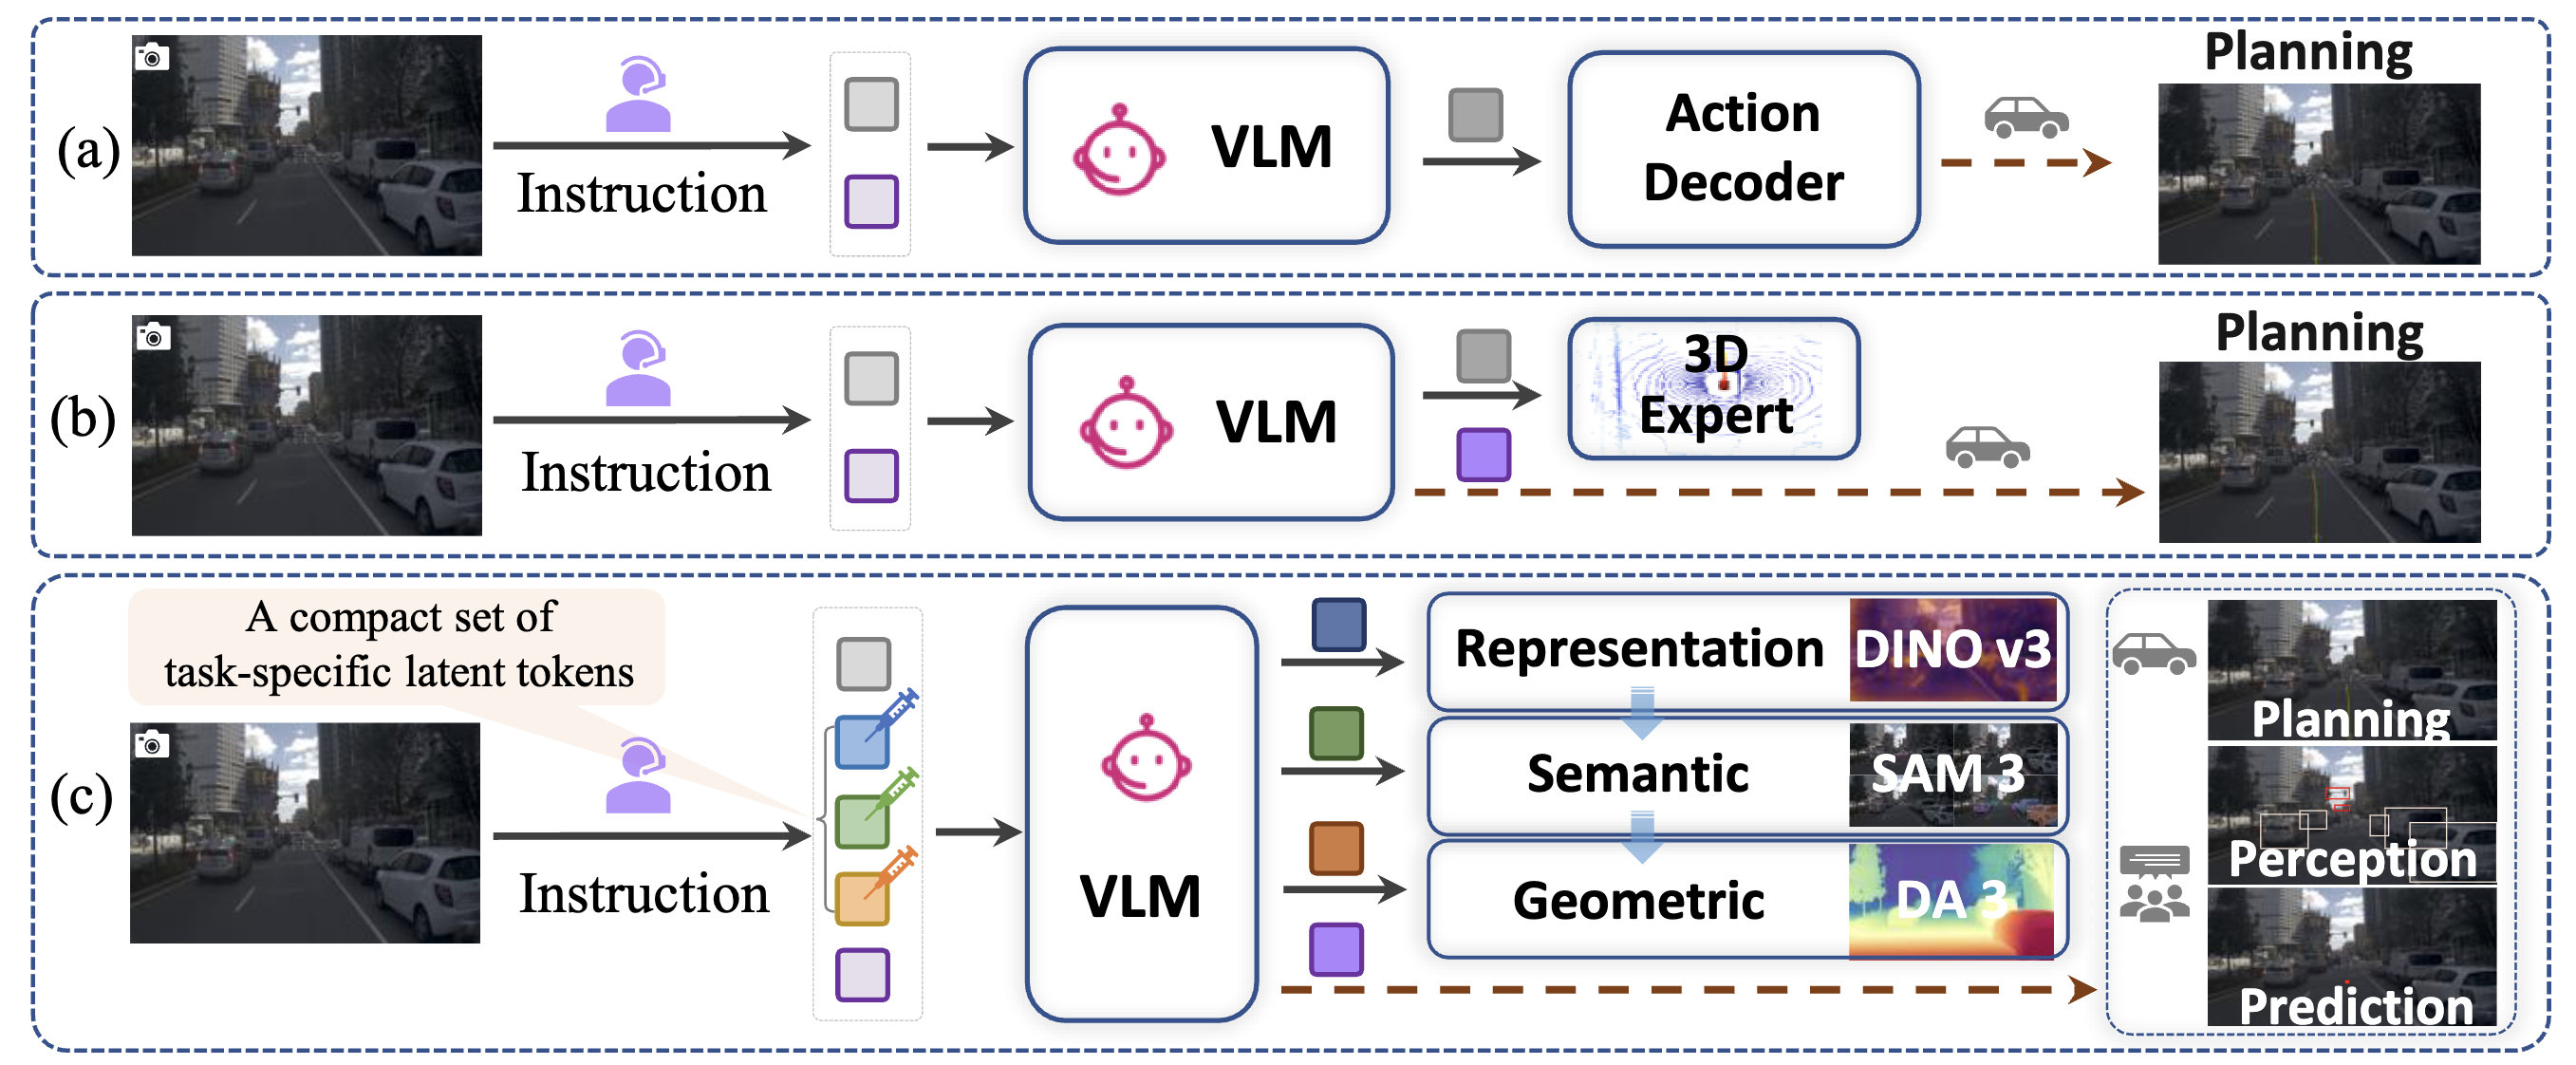 |
Think Densely, Act Sparsely: Latent Expert Cognitive Chains for Vision-Language-Action Autonomous Driving
|
 |
OneVL: One-Step Latent Reasoning and Planning with Vision-Language Explanation
|
 |
Towards Stable Source-Free Domain Adaptive Semantic Segmentation |
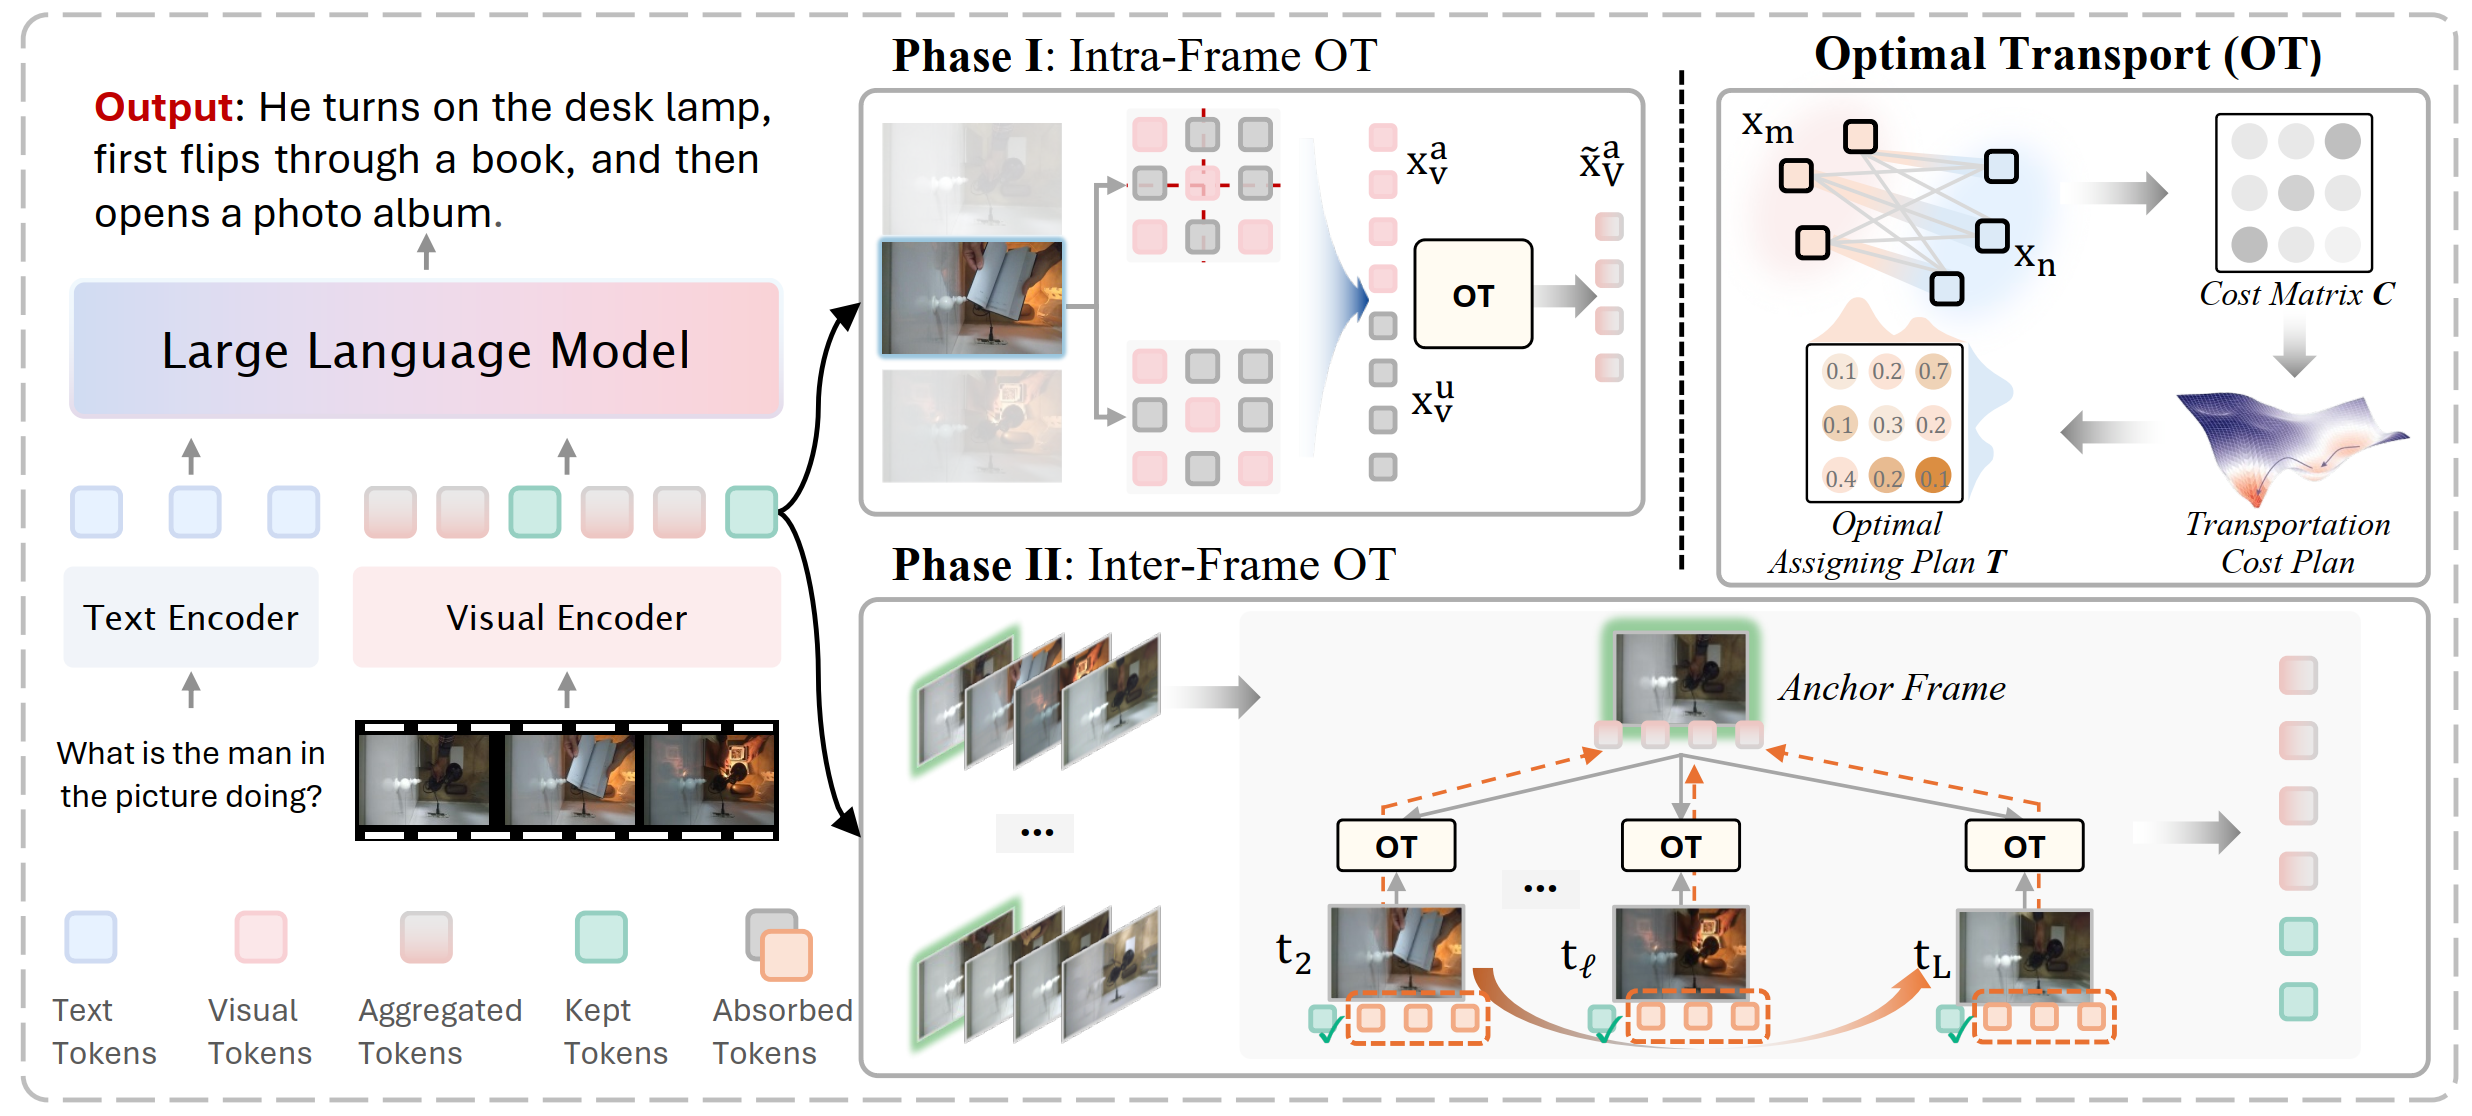 |
Token Reduction via Local and Global Contexts Optimization for Efficient Video Large Language Models |
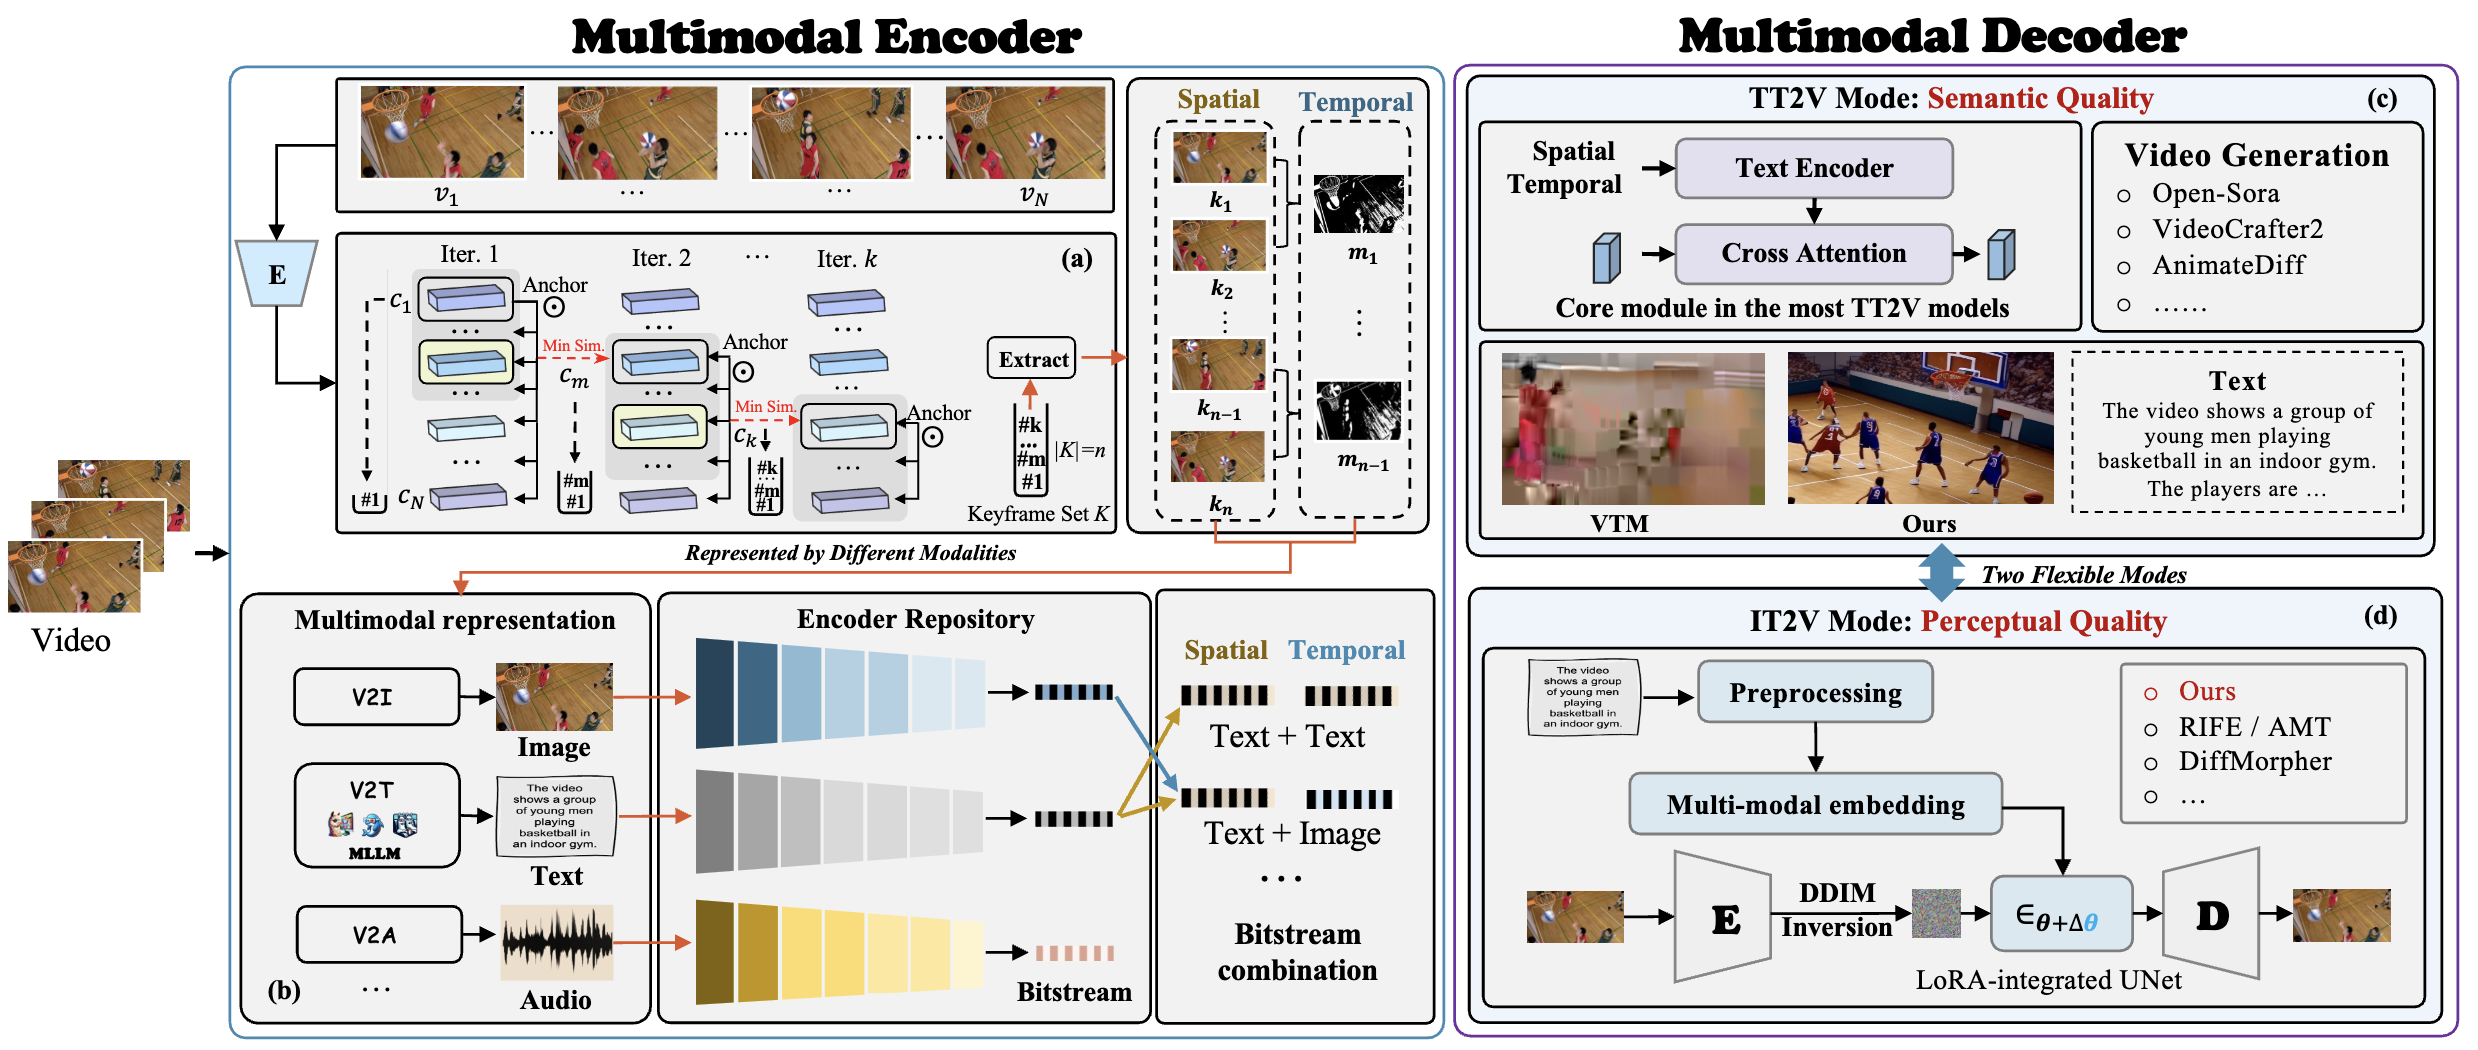 |
When Video Coding Meets Multimodal Large Language Models: A Unified Paradigm for Video Coding |
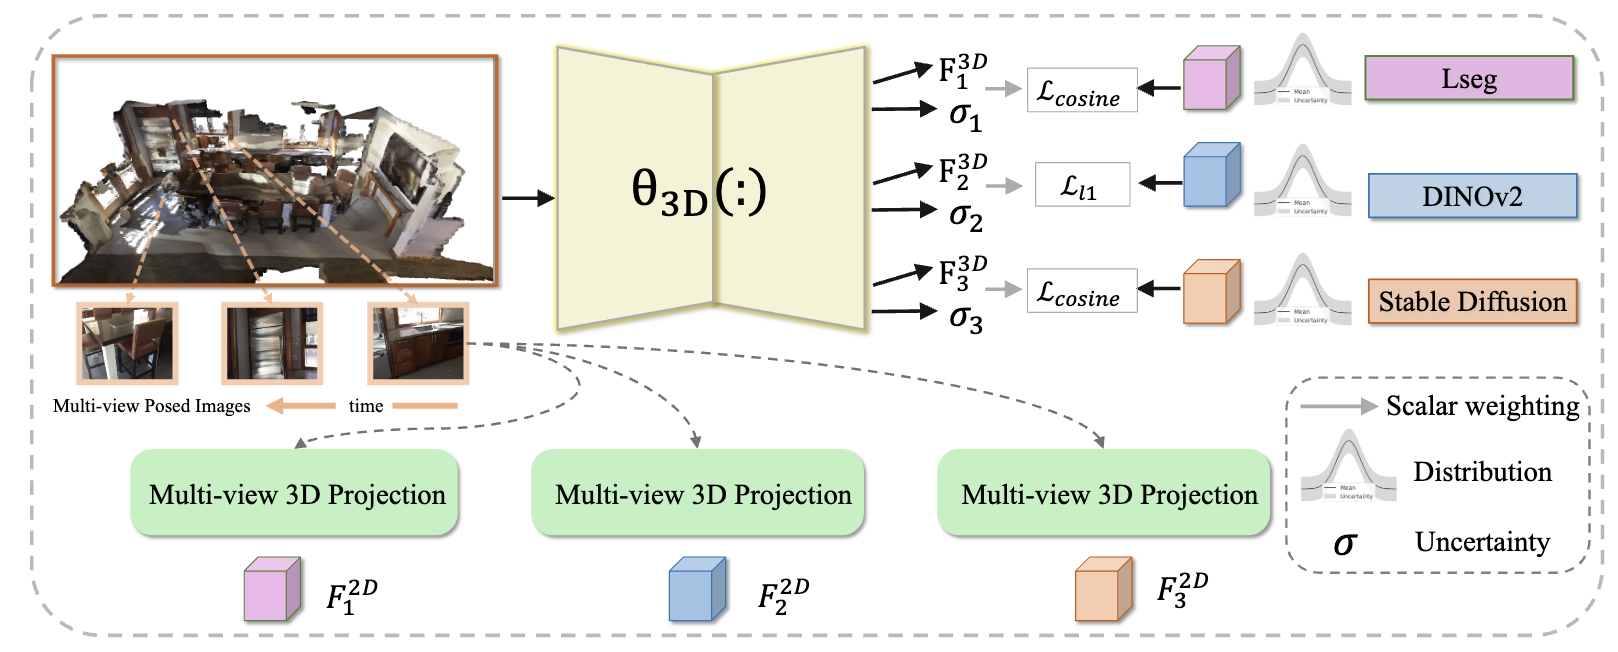 |
Cross-Modal and Uncertainty-Aware Agglomeration for Open-Vocabulary 3D Scene Understanding |
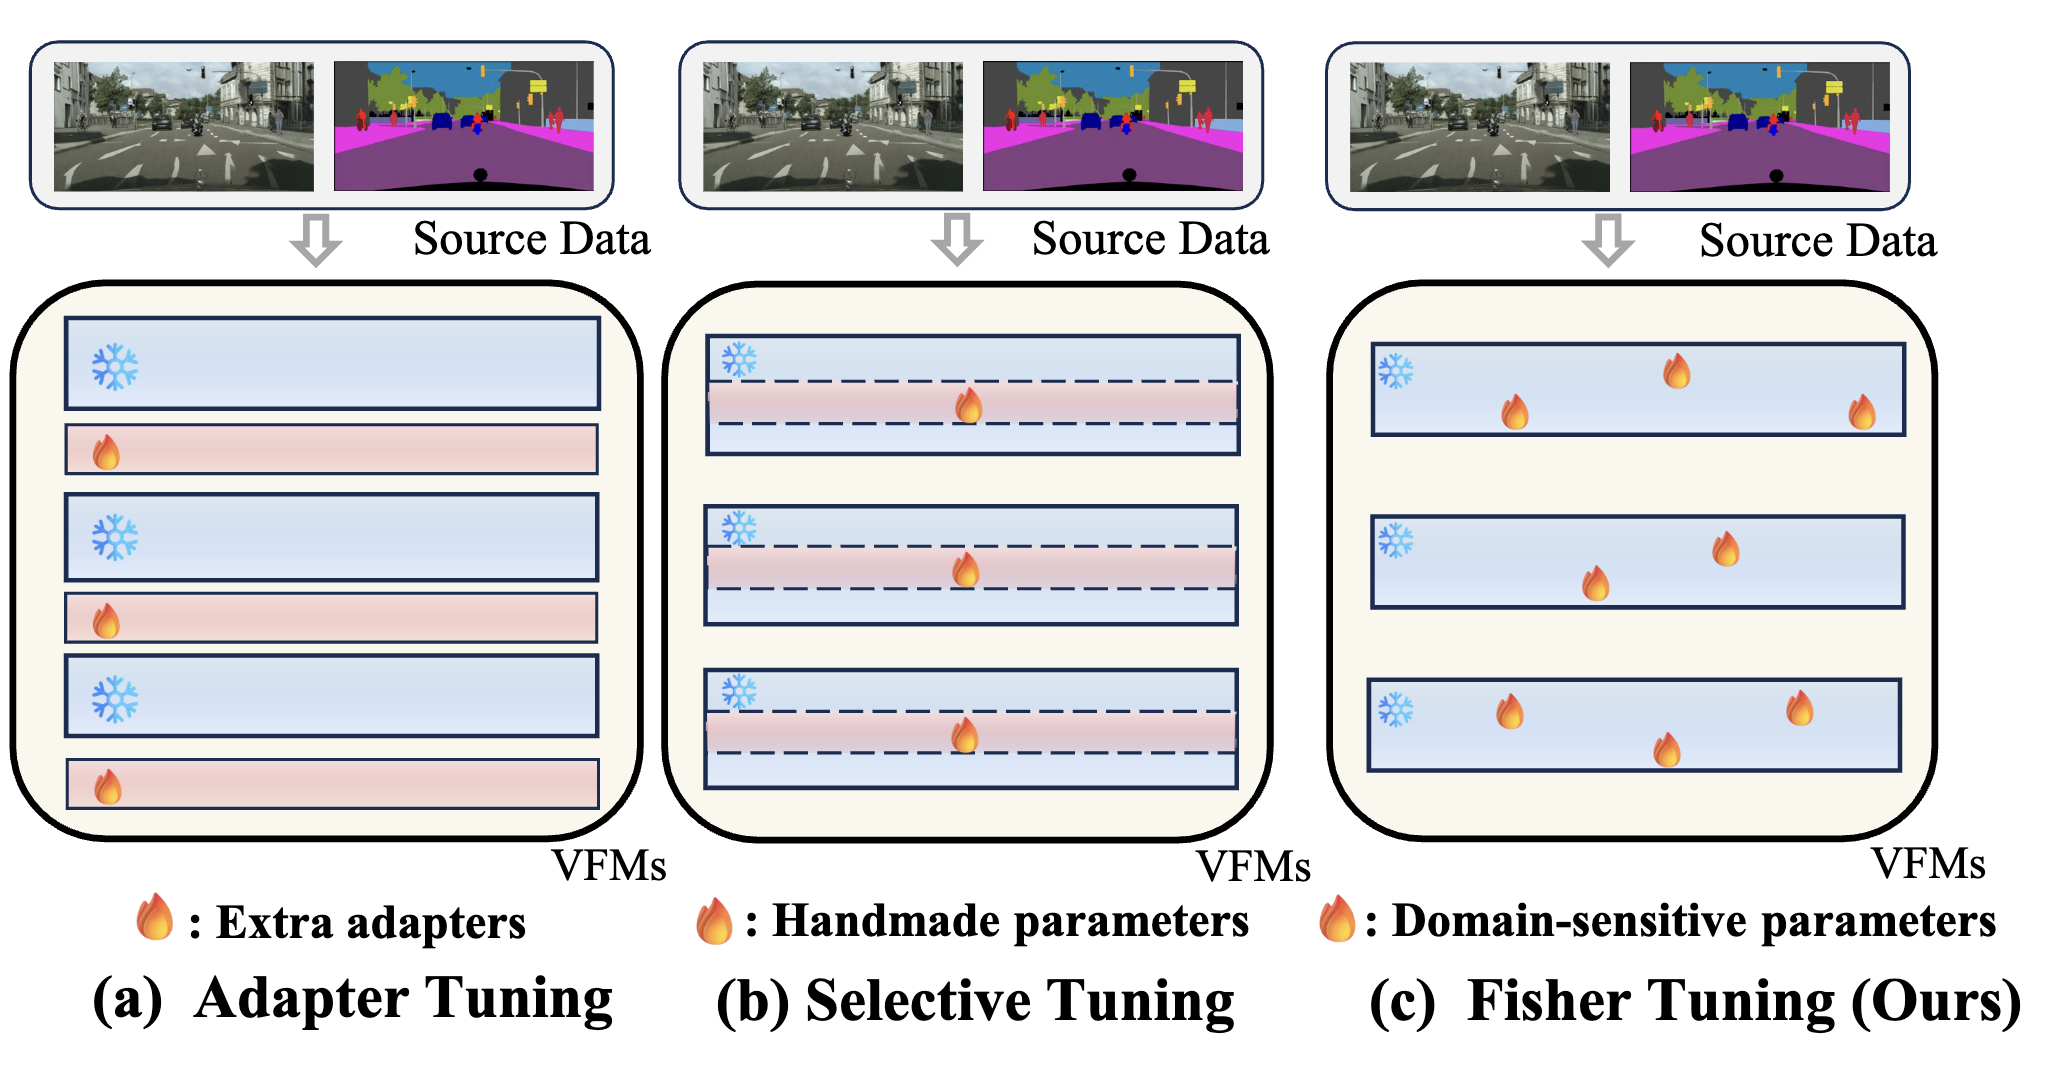 |
FisherTune: Fisher-Guided Robust Tuning of Vision Foundation Models for Domain Generalized Segmentation |
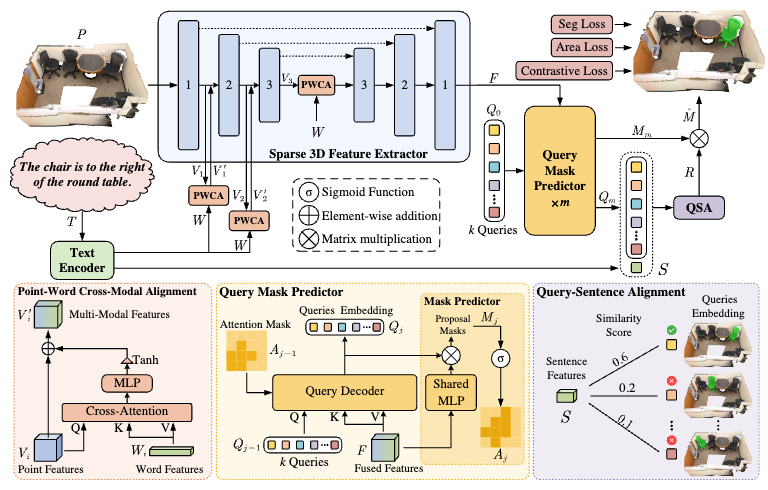 |
LESS: Label-Efficient and Single-Stage Referring 3D Instance Segmentation |
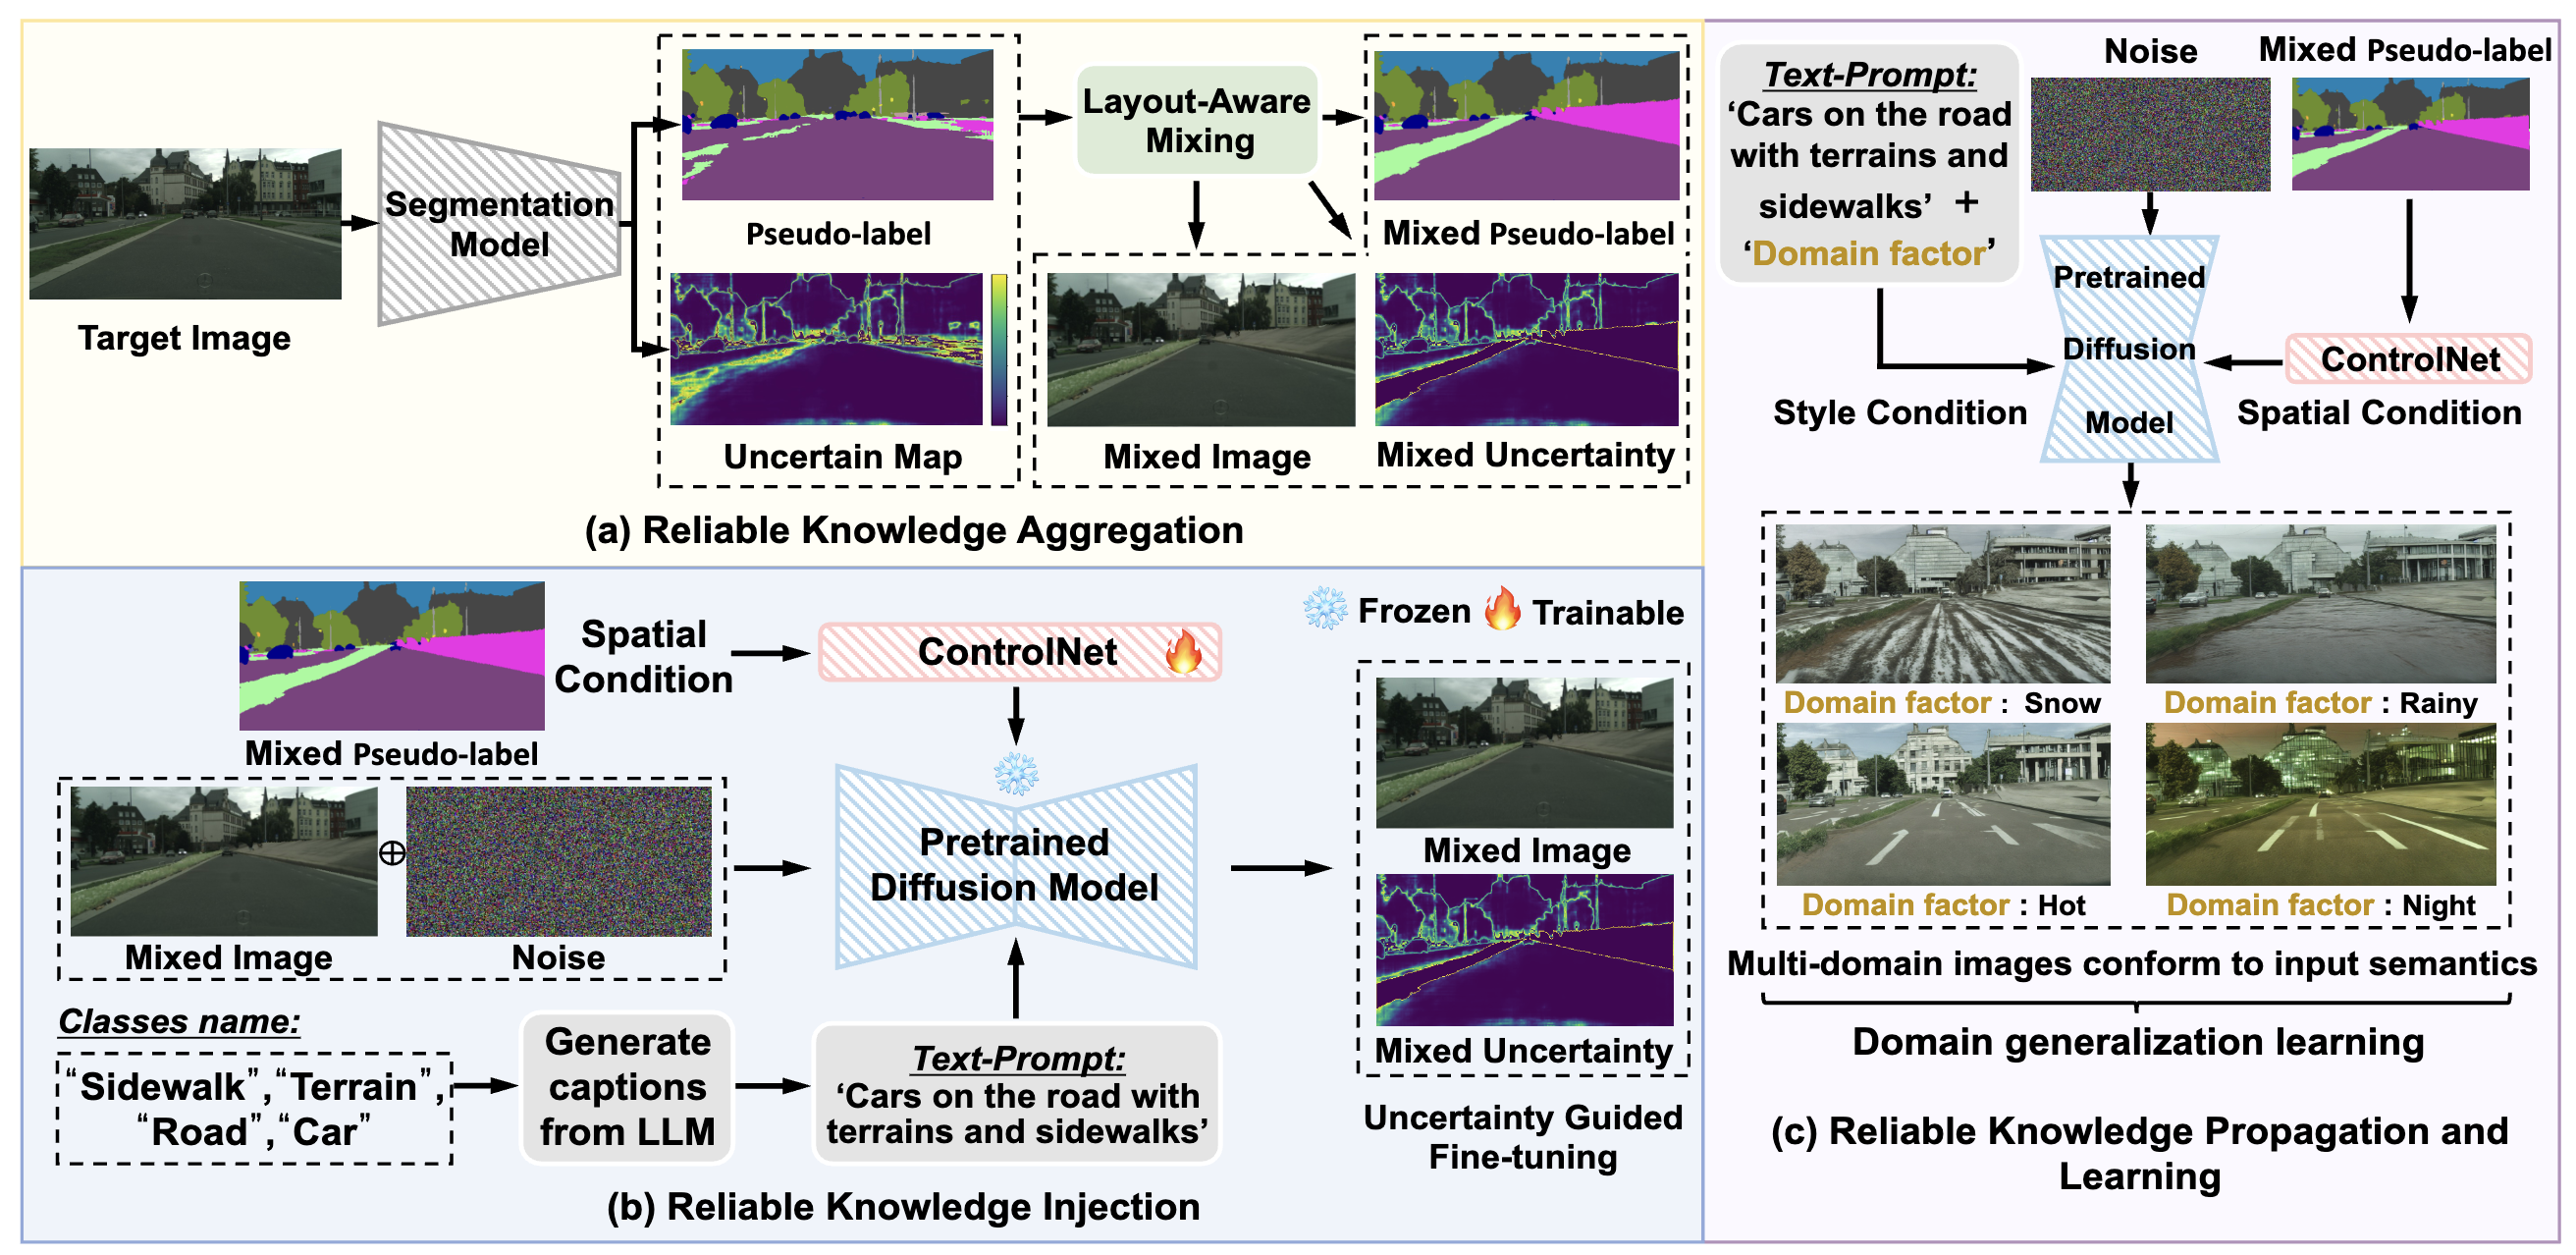 |
Generalized Source-free Domain-adaptive Segmentation via Reliable Knowledge Propagation
|
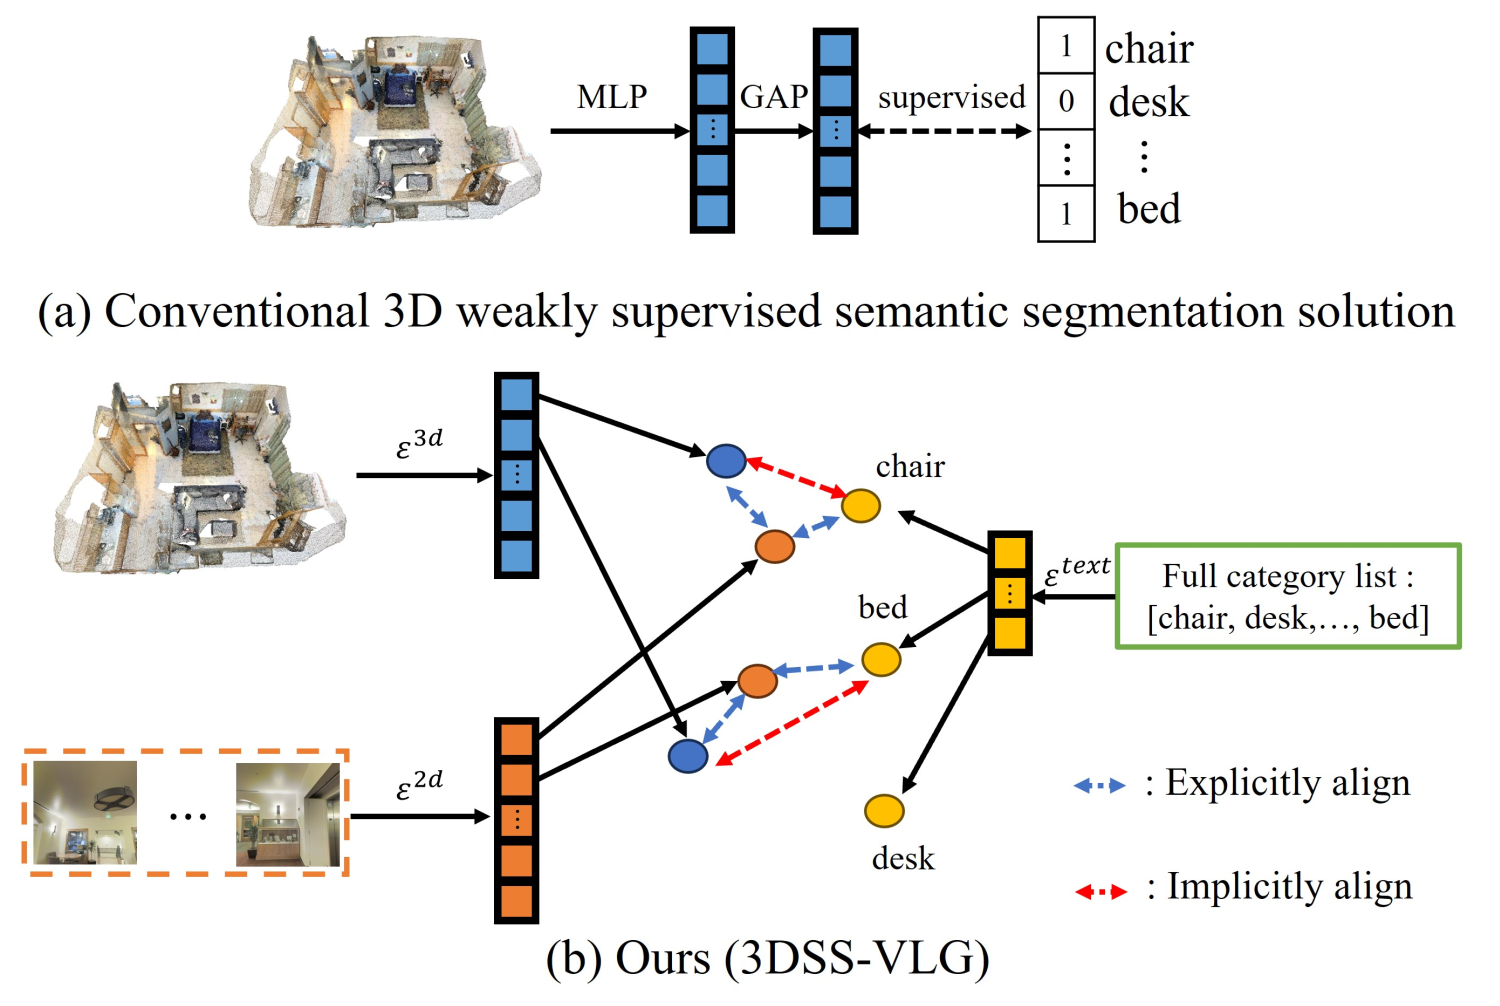 |
3D Weakly Supervised Semantic Segmentation with 2D Vision-Language Guidance
|
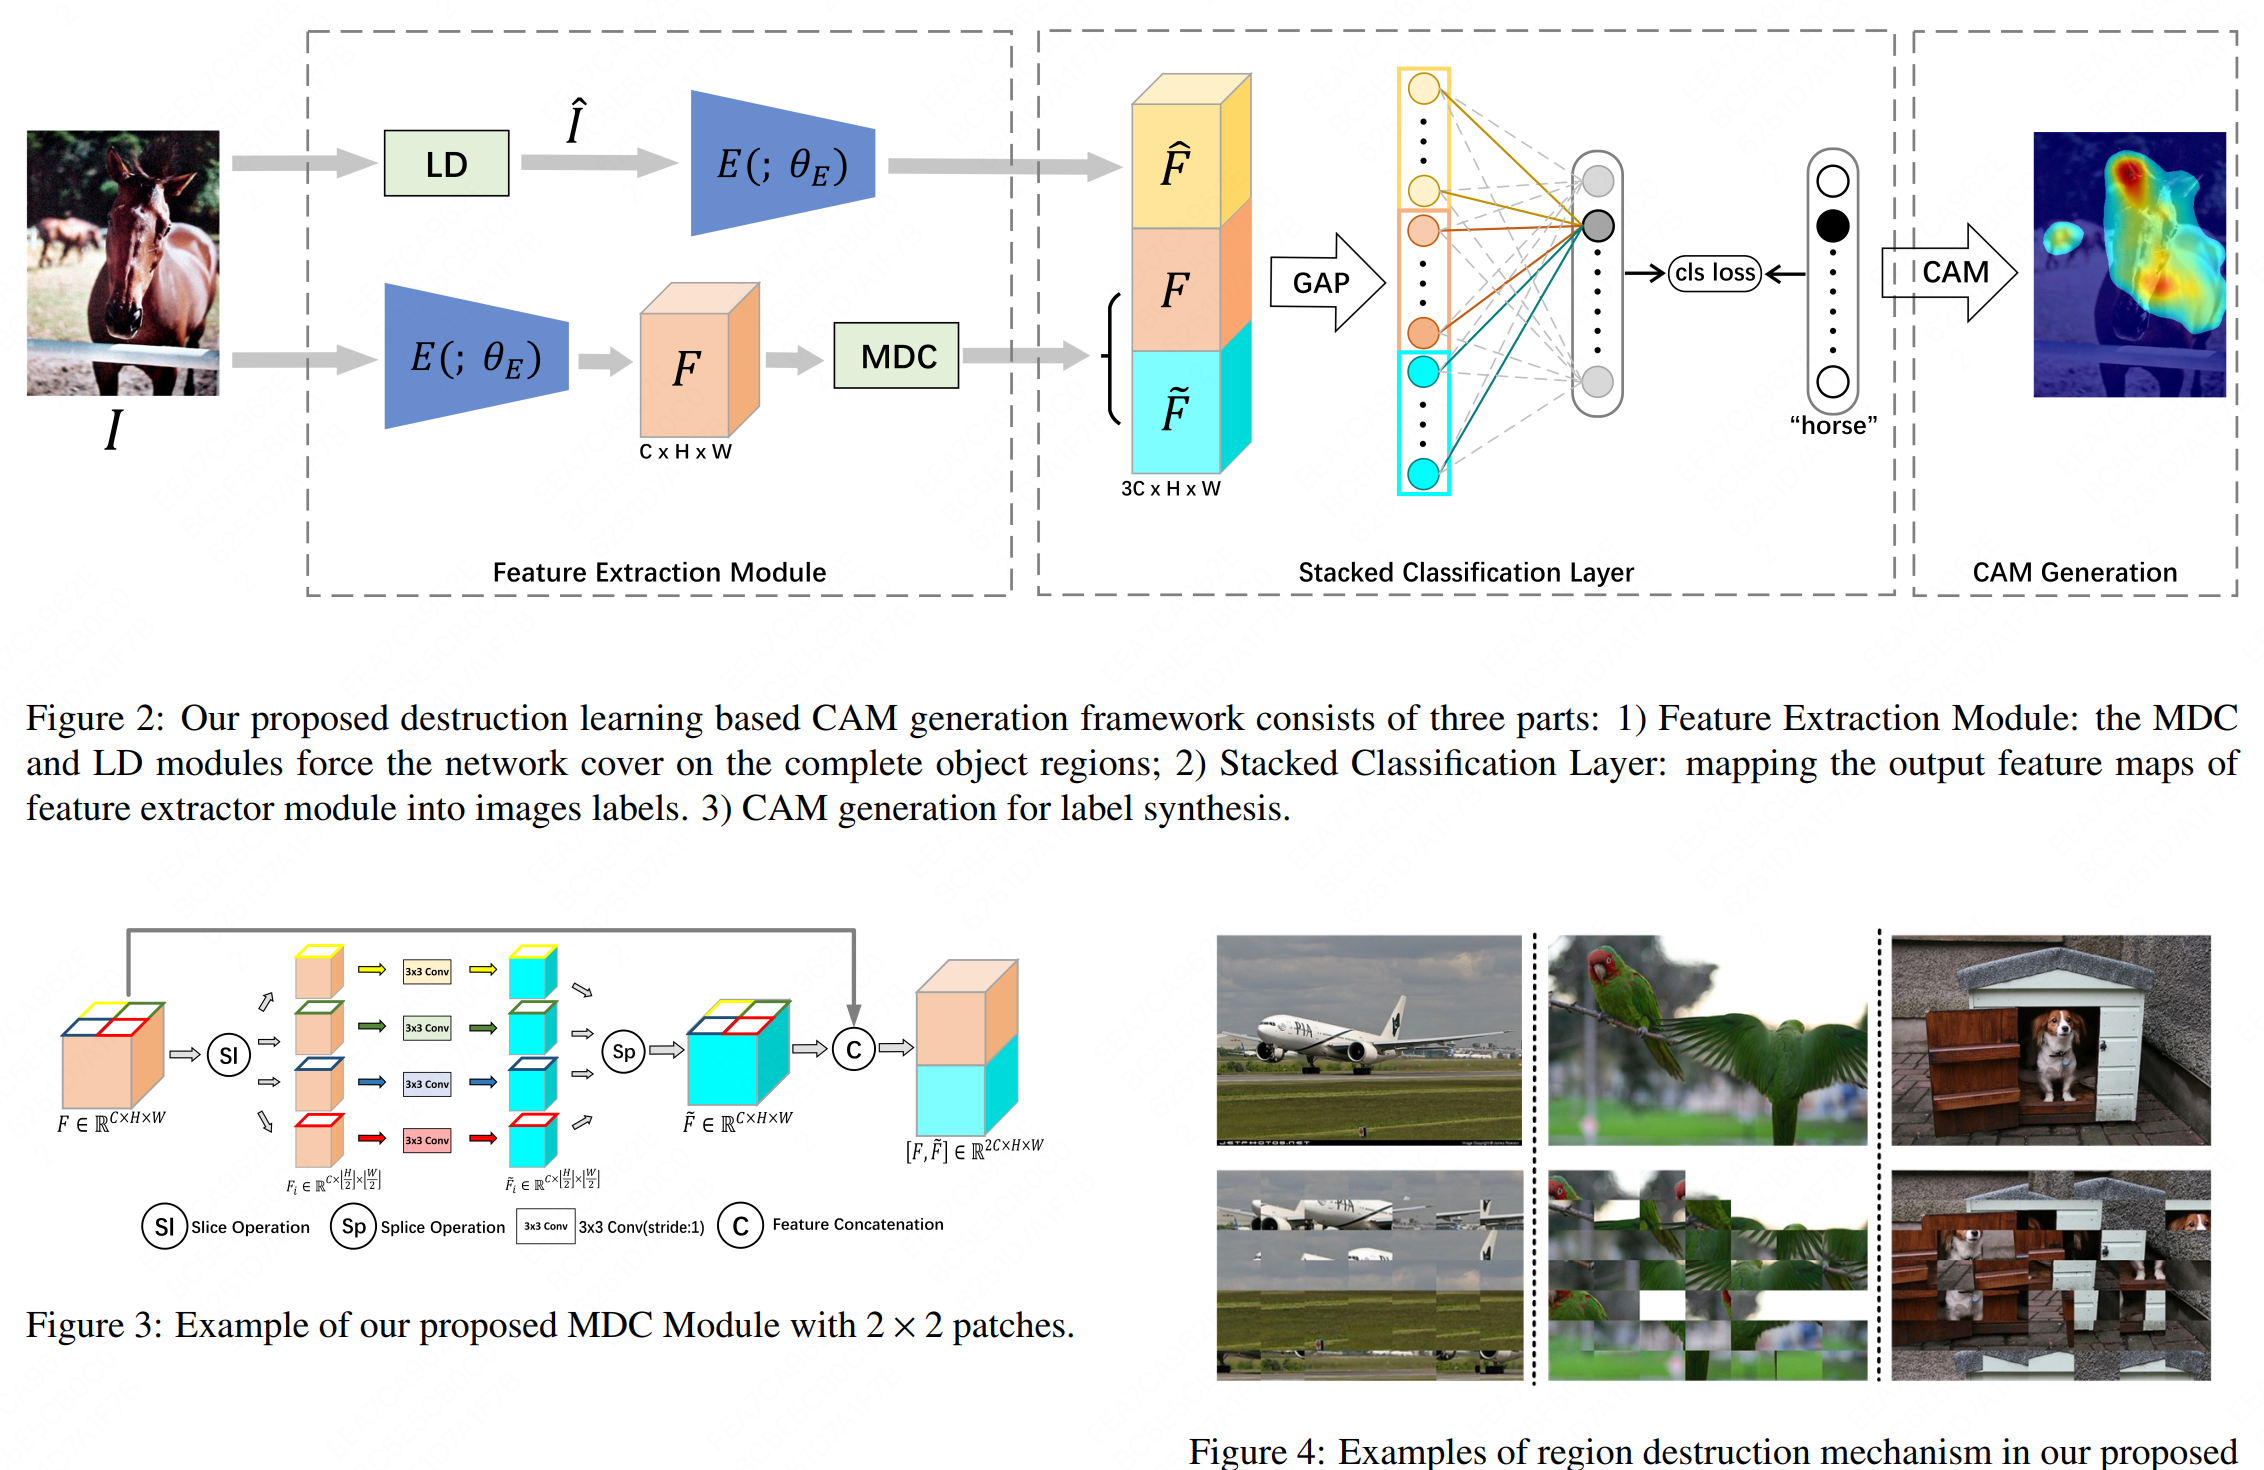 |
Weakly Supervised Semantic Segmentation via Self-Supervised Destruction Learning |
 |
Expansion and Shrinkage of Localization for Weakly-Supervised Semantic Segmentation |
 |
Weakly Supervised Semantic Segmentation via Progressive Patch Learning |
 Xiaomi, Autonomous Driving and Robotics Department
 Meituan